
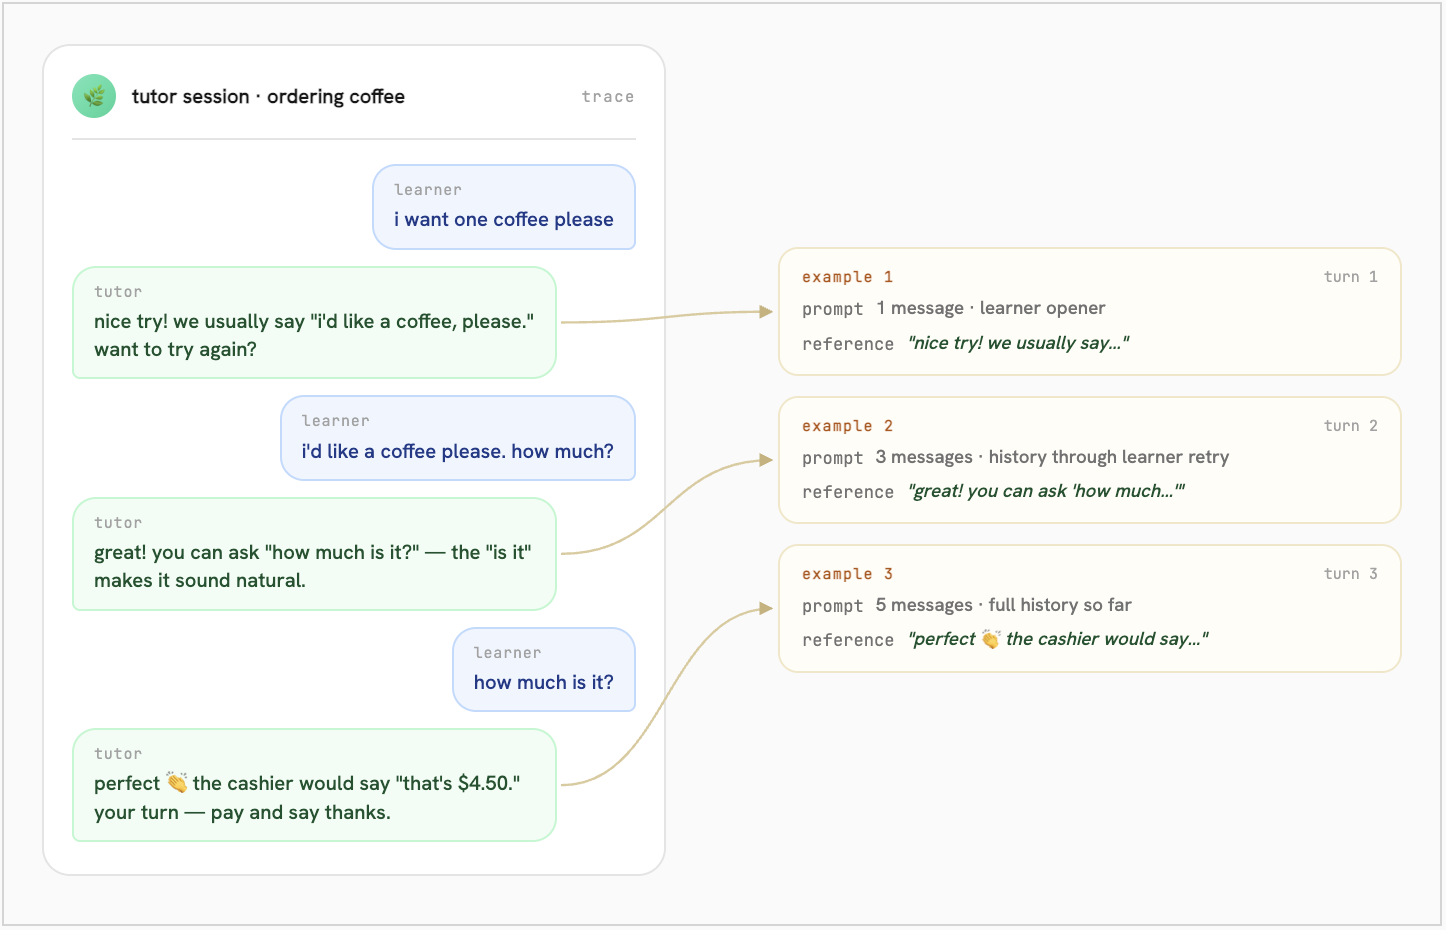
elsa · language-model post-training
a language tutor built for beginner learners
elsa used production conversations to adapt a model to each learner’s level, with half the inference cost and latency.
read the post →no minimum commitment. ask for the gpus you need and your run starts.
we pool spot capacity across providers and regions. we automatically resume your run wherever there's a gpu free.
the catch is that they can be taken back at any time.
we snapshot your whole process at the os-level, not just your weights. when a machine is preempted, we bring up another and resume from the last snapshot within minutes.
monitor your job and machine with realtime logging plus observability into hardware-level metrics. we make it easy and quick for you to debug and profile your workloads, regardless of where in the stack you operate.
we auto-instrument your training workloads so you can see reward and loss curves move in real time, as well as browse the rollouts your model is producing while it trains.
import castform

container = castform.Container(
    name="miles-dev",
    image=castform.Image.from_registry("radixark/miles:latest")
        .add_local_dir("./training", "/workspace/training"),
    gpu="H100:8",
)

container.run(["python", "train.py"])elsa used production conversations to adapt a model to each learner’s level, with half the inference cost and latency.
read the post →
using postgres data in neon, a small open model matched frontier retrieval accuracy at a fraction of the inference cost.
read on neon.com →tell us a little about you and we'll be in touch.
we'll email you when there's a spot for you. your $100 in free credits will be waiting.
we're ml researchers and engineers from the stanford ai lab, google brain and roblox. we've run thousands of training jobs and got fed up with how difficult it was to get compute, both in terms of availability and in consistency of prices.